Fault Management & Media Engine Blueprint
Clean-Room Technical Deep Dive: High-Concurrency Fault Management, Semantic Caching & Media Discovery
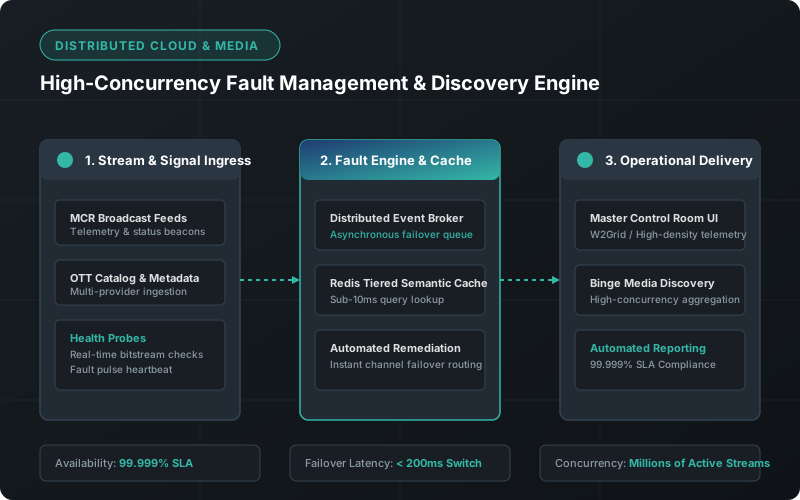
1. Business & Technical Context
National broadcast networks and large-scale OTT streaming hubs require stringent 99.999% SLA availability. Minor signal dropouts, packet jitter, or metadata catalog desynchronization across multi-provider streaming feeds trigger immediate broadcast failure and viewer dissatisfaction. The operational goal was establishing an automated Master Control Room (MCR) telemetry platform that isolates broadcast anomalies in real time, generates compliance reports, and orchestrates seamless OTT media discovery for millions of concurrent viewers.
2. Architectural Decisions & Trade-offs
- Tiered Redis Semantic Caching: High-velocity media discovery requests bypass primary transactional databases through an in-memory Redis cluster with optimized TTL and LRU eviction, delivering sub-10ms query responses.
- Asynchronous Failover Orchestration: Implemented event-driven message queuing for stream health heartbeats. Upon detecting signal distortion, the system triggers automated route failover without human operator intervention.
- High-Density Operator Console: Developed high-performance operational dashboards (W2Grid & React) displaying multi-channel health telemetry with sub-second refresh rates.
3. Engineering Challenges & Mitigations
- Thundering Herd During Major Live Events: Millions of concurrent users searching media simultaneously risked backend saturation. Mitigated by dynamic cache stampede prevention and pre-warmed semantic caches.
- Zero-Downtime Hot Deployments: Media streaming operations cannot afford maintenance downtime. Implemented blue-green canary deployment pipelines with automatic health rollback.
- Data Synchronization Across Heterogeneous OTT APIs: Built resilient normalization adapters with circuit breakers to insulate core services from intermittent third-party OTT provider failures.
4. Measurable Outcomes & Metrics
Initiative Metadata
- Role: Technical Lead & Systems Architect
- Pod Scope: Distributed Media & Systems Pod
- Domain: Distributed Cloud & High-Concurrency Media
- Stack: React, Redux, Redis, Microservices
- Platforms: Tata Sky Binge & MCR Suite
Technical Leadership Discussion
Interested in high-concurrency systems, fault tolerance strategies, or media discovery architectures?
Initiate Executive Discussion